Bengio's Neural Probabilistic Language Model (2003)
In 2003, Yoshua Bengio, Réjean Ducharme, Pascal Vincent, and Christian Jauvin published A Neural Probabilistic Language Model in the Journal of Machine Learning Research (JMLR).
Today, this paper is universally recognized as the foundational pillar of modern deep learning for natural language processing. It introduced two concepts that remain at the heart of modern Large Language Models:
- Distributed continuous word representations (word embeddings), replacing discrete orthogonal symbols with dense vectors in .
- Probability density estimation via neural networks, replacing combinatorial frequency counting tables with a smooth, differentiable function that generalizes across unseen combinations.
This article provides an end-to-end technical dissection of Bengio et al.’s model: the problem it solved, its mathematical formulation, its dual-path architecture, its gradient mechanics, and the computational bottlenecks that catalyzed twenty years of NLP research.
1. The Pre-2003 Paradigm: The Curse of Dimensionality
A language model estimates the joint probability distribution over sequences of words drawn from a finite vocabulary :
Before Bengio’s work, language modeling was dominated by statistical n-gram models, which relied on a stationary Markov assumption of order :
Where denotes the count of exact phrase occurrences in a training corpus.
Why Discrete Counting Collapses
Count-based statistical language modeling was crippled by two fundamental limitations:
1. Exponential State-Space Explosion
The conditioning context consists of tokens. The number of free parameters required to store conditional probabilities for an n-gram table is:
For a modest vocabulary of and a modest context window of (4 conditioning words), the parameter space demands:
Even the largest internet corpora can observe only an infinitesimally tiny fraction of these combinations. The vast majority of valid linguistic combinations never appear in the training data, leading to extreme sparsity.
2. Orthogonality and Zero Semantic Generalization
In discrete statistical models, words are symbolic atoms represented by standard basis (one-hot) vectors:
The Euclidean distance between any two distinct words is always:
And their inner product is zero:
Because the representation contains no notion of semantic similarity or syntactic distance, observation of:
- “The cat walked across the street”
imparts zero statistical evidence about the likelihood of:
- “The kitten walked across the street”
Traditional techniques attempted to patch this using smoothing algorithms (Jelinek-Mercer interpolation, Good-Turing discounting, and Modified Kneser-Ney). However, smoothing merely backs off to lower-order n-grams (). It redistribution rules are purely frequency-driven; it cannot share statistical strength across semantically analogous sentences.
2. Bengio’s Conceptual Leap: Distributed Representations
Bengio et al. proposed to solve both the curse of dimensionality and the generalization crisis simultaneously through three interrelated ideas:
- Continuous Feature Vectors: Associate each word with a real-valued distributed feature vector , where (typically in 2003; now ).
- Smooth Neural Mapping: Formulate the conditional probability as a continuous, differentiable neural network function taking the concatenated feature vectors as input.
- Simultaneous Optimization: Learn the word feature vectors and the weights of the neural probability function together using gradient descent.
The Continuous Probability Surface
Because the neural network is composed of continuous, smooth operations (, linear matrix multiplications, softmax), small perturbations in the input feature vectors produce small, smooth changes in the predicted output probabilities:
If the model encounters “The cat walked across the street” during training, backpropagation adjusts the coordinates of , , and . Because naturally clusters near due to shared surrounding contexts elsewhere in the corpus, the model automatically assigns high probability to “The kitten walked across the street”, even if that exact sequence of words was never observed in training.
3. The Architecture of the Neural Language Model
Below is the complete architectural layout of Bengio’s 2003 Neural Probabilistic Language Model (NPLM):
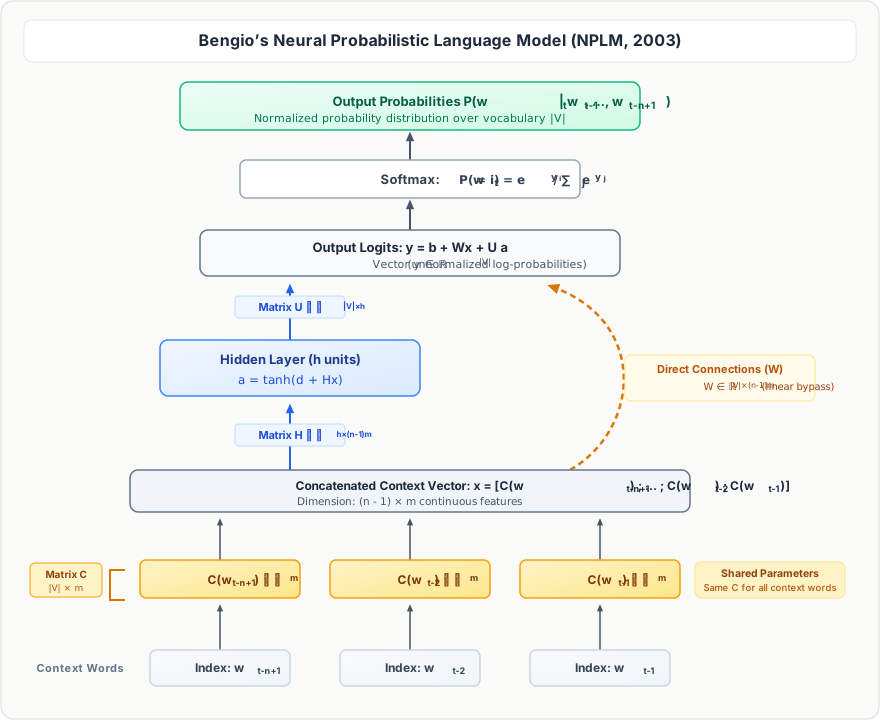
The model consists of four sequential stages: Input Lookup, Feature Concatenation, Dual-Pathway Processing, and Softmax Normalization.
3.1. Word Feature Lookup Matrix ()
Let the context consist of the previous words:
Each word is an integer index in .
The feature lookup matrix is:
Where row (or column) represents the -dimensional continuous distributed embedding of word .
Crucial Architectural Detail: The exact same matrix is shared across all input positions. Whether a word appears at position or position , its semantic identity is projected through the identical embedding matrix .
For word , the lookup operation extracts its embedding:
3.2. Context Concatenation ()
The extracted embedding vectors are concatenated in temporal order into a single composite context vector :
The dimensionality of scales linearly with context length:
3.3. Dual-Pathway Processing: Hidden Layer + Direct Connections
Bengio’s model maps the context vector to unnormalized output logits using two parallel pathways:
Pathway 1: The Non-Linear Hidden Layer
The context vector feeds into a fully connected layer with hidden units and a hyperbolic tangent () activation:
- : Hidden weight matrix.
- : Hidden layer bias vector.
- : Activated hidden states.
The hidden representation is then projected to vocabulary space through matrix :
- : Output projection matrix.
Pathway 2: Direct Linear Skip Connections ()
In addition to the non-linear hidden path, Bengio introduced a direct linear bypass connecting context directly to output logits:
- : Direct skip connection matrix.
Why Did Bengio Include Direct Connections? The direct connection provides a linear shortcut. It allows the model to easily fit simple linear dependencies—effectively learning a smooth linear n-gram / unigram prior—leaving the hidden layer free to dedicate its capacity to learning non-linear cross-feature interactions. (Bengio noted that setting works, but keeping yields slightly faster convergence and lower perplexity).
3.4. Logits and Softmax Normalization
Combining both pathways along with an output bias vector , the total score (logit) vector is:
For each individual word , its logit is:
Where is the -th row of , and is the -th row of .
Finally, the logits are normalized into a valid categorical probability distribution via the Softmax function:
4. Parameter Breakdown and Dimensionality
Let us examine the total parameter inventory :
| Parameter | Matrix Dimensions | Description | Scale in Bengio 2003 |
|---|---|---|---|
| $ | \mathcal{V} | \times m$ | |
| Context-to-hidden weight matrix | Dependent on context size | ||
| Hidden layer bias vector | Size of hidden dimension | ||
| $ | \mathcal{V} | \times h$ | |
| $ | \mathcal{V} | \times (n-1)m$ | |
| $ | \mathcal{V} | \times 1$ |
Total Free Parameters Formula:
Factoring by vocabulary size :
Concrete Numerical Example (From Bengio et al., 2003)
Consider typical hyperparameters from the paper:
- Vocabulary size:
- Context order: (so context words)
- Feature vector size:
- Hidden units:
Calculating each component:
- :
- :
- :
- :
- :
- :
Notice where the bulk of the parameter weight lies:
- The hidden layer has only 12,000 weights ().
- The vocabulary-dependent matrices () account for over 99.7% of all model parameters!
Unlike count tables that explode exponentially as , Bengio’s neural model scales linearly with context length: .
5. Mathematical Mechanics: Loss and Backpropagation
The training objective is penalized maximum log-likelihood across a corpus of tokens:
For a single training example at time where target token is , the negative log-likelihood loss is:
5.1. Logit Gradients
Differentiating with respect to logit :
Let vector . Its components are:
Where is the Kronecker delta. The error signal is simply the predicted probability minus the true one-hot target.
5.2. Gradients for Output Weights and Hidden Units
Applying the chain rule:
The gradient propagating back into the hidden activation vector :
Passing through the non-linear hyperbolic tangent activation where :
5.3. Backpropagation into the Context Vector
Both the direct connection and the hidden layer contribute to the gradient of the concatenated input vector :
5.4. Updating the Word Embedding Matrix
Because is the concatenation of feature vectors:
We slice into chunks of dimension :
Sparse Gradient Updates: In a vocabulary of 50,000 words, only the word vectors present in the current context receive non-zero gradient updates at step : All other rows in remain untouched during this step.
6. The Computational Bottleneck: The Output Softmax
While Bengio’s NPLM conquered the curse of dimensionality, it ran directly into a severe computational barrier: the cost of computing the denominator in the softmax function.
To perform a single parameter update at step :
- The model must compute the logit for every single word in the entire vocabulary .
- This requires the full matrix-vector product and , which costs:
In 2003, modern GPUs did not exist for machine learning. Training Bengio’s model with on 14 million words took 3 weeks on a cluster of 40 CPUs running parallelized asynchronous stochastic gradient descent.
                      The 2003 Softmax Bottleneck:

   Hidden state a (h = 100)
             │
             ▼
   Matrix Multiply: U ∈ ℝ^{|V| × h}   ◄── Computing scores for ALL 18,000+ words
             │                            at EVERY training step!
             ▼
   Unnormalized Logits y ∈ ℝ^{|V|}
             │
             ▼
   Denominator Sum: ∑_{j=1}^{|V|} exp(y_j)
The Inventions Spawned by this Bottleneck
This exact bottleneck stimulated a decade of groundbreaking machine learning research to approximate or accelerate the softmax:
- Hierarchical Softmax (Morin & Bengio, 2005; Mnih & Hinton, 2009): Organized the vocabulary into a balanced binary tree or WordNet hierarchy. Evaluating word probability required only walking from root to leaf, reducing complexity from to .
- Importance Sampling & NCE (Noise-Contrastive Estimation, Gutmann & Hyvärinen, 2010; Mnih & Teh, 2012): Transformed the multi-class density estimation problem into binary classification (discriminating real target tokens from noise samples).
- Negative Sampling in Word2Vec (Mikolov et al., 2013): Simplified NCE by sampling only negative tokens per target word, completely bypassing the denominator and allowing Word2Vec to train on billions of tokens in hours on a single desktop.
7. Experimental Results: Does It Actually Work?
Bengio et al. tested their model on two standard benchmarks of the time:
- Brown Corpus: 1,181,041 words; vocabulary pruned to .
- Associated Press (AP) News: 14 million words; vocabulary pruned to .
Evaluation was performed using Perplexity (PPL), which measures the inverse geometric mean probability assigned to the test tokens:
Lower perplexity indicates a superior, more confident predictive model.
Key Results on AP News (Validation Perplexity)
| Model Architecture | Context Size () | Validation Perplexity | Relative Improvement |
|---|---|---|---|
| Smoothed Trigram (Kneser-Ney) | 125.2 | Baseline | |
| Smoothed 4-gram (Kneser-Ney) | 123.0 | ||
| Smoothed 5-gram (Kneser-Ney) | 121.5 | ||
| Bengio Neural LM (MLP alone) | () | 113.2 | |
| Bengio Neural LM (Interpolated with N-gram) | 109.4 |
Critical Findings from the Paper:
- Dramatic Perplexity Drop: The neural language model achieved a roughly 10% to 20% relative perplexity reduction over state-of-the-art interpolated and Kneser-Ney smoothed n-grams.
- Model Ensembling / Interpolation: Bengio discovered that interpolating the predictions of the neural model with an n-gram model: outperformed either model alone. The n-gram was effective at memorizing frequent local idiomatic bigrams/trigrams, while the neural network generalized across broad semantic contexts.
- Emergence of Semantic Vector Spaces:
When Bengio visualized the 30-dimensional learned word representations using 2D projections, the vectors naturally formed semantic clusters:
- Grammatical parts of speech grouped together (determiners with determiners, verbs with verbs).
- Synonyms and co-hyponyms (“cat”, “dog”, “rabbit”) mapped to adjacent coordinates in the vector space.
8. Bengio’s Model vs. The Modern Transformer
How does Bengio’s 2003 formulation compare to modern Large Language Models like GPT-4 or LLaMA?
| Dimension | Bengio NPLM (2003) | Modern Decoder Transformer (e.g. GPT / LLaMA) |
|---|---|---|
| Word Representation | Matrix $C \in \mathbb{R}^{ | \mathcal{V} |
| Context Aggregation | Fixed-length vector concatenation: | Causal Multi-Head Self-Attention: |
| Context Length () | Fixed window of words | Dynamic sequence of to tokens |
| Non-Linear Transform | Single shallow hidden layer: | Deep stacked Transformer blocks ( layers) with SwiGLU / GeLU MLPs |
| Output Head | Logits | Linear head with tied or untied weights: |
| Probability Function | Softmax over vocabulary $ | \mathcal{V} |
| Optimization | Maximizing log-likelihood via SGD | Maximizing log-likelihood via AdamW + FP8/BF16 mixed precision |
What Changed?
- From Concatenation to Self-Attention: Bengio’s concatenation assumed a rigid context size (). A token at position occupied fixed dimensions in , while a token at occupied . There was no position-invariant relational reasoning. Self-attention replaced concatenation with content-based pairwise routing.
- From Words to Subwords: Bengio used full dictionary words, leading to large out-of-vocabulary (OOV) issues or huge matrices. Modern LLMs use subword tokenization (Byte-Pair Encoding, WordPiece), fixing typically between 32,000 and 128,000 while maintaining open-vocabulary coverage.
- Depth: Bengio’s model was 2 layers deep (embedding hidden output). Modern LLMs stack dozens of Transformer layers with residual connections and RMSNorm.
What Remained Identical?
The macro-objective is fundamentally unchanged:
- Every token is mapped to a continuous vector via an embedding table.
- A parameterized network computes logits across the vocabulary.
- The model is trained via self-supervised autoregressive next-token prediction using cross-entropy loss over a Softmax distribution.
9. Summary & Enduring Legacy
Yoshua Bengio’s 2003 paper accomplished three historic feats:
- Proved the viability of distributed representations for language: It validated the connectionist hypothesis (Hinton, 1986) on real-world, large-scale linguistic data.
- Broke the curse of dimensionality: By treating probability estimation as a continuous regression problem rather than discrete combinatorial counting, it introduced semantic generalization to machine learning.
- Laid the foundational template for all modern generative models: Every neural architecture that followed—Word2Vec, LSTMs, BERT, and GPT—is an evolution of the distributed probabilistic paradigm introduced in this landmark paper.
References
- Bengio, Y., Ducharme, R., Vincent, P., & Jauvin, C. (2003). A Neural Probabilistic Language Model. Journal of Machine Learning Research (JMLR), 3(Feb), 1137-1155.
- Hinton, G. E. (1986). Learning distributed representations of concepts. Proceedings of the eighth annual conference of the cognitive science society, 1, 1-12.
- Morin, F., & Bengio, Y. (2005). Hierarchical Probabilistic Neural Network Language Model. AISTATS.
- Mikolov, T., Chen, K., Corrado, G., & Dean, J. (2013). Efficient Estimation of Word Representations in Vector Space. arXiv:1301.3781.
- Vaswani, A., et al. (2017). Attention Is All You Need. Advances in Neural Information Processing Systems (NeurIPS).